The Death of the Wrapper: Architecting True AI-Native Backends
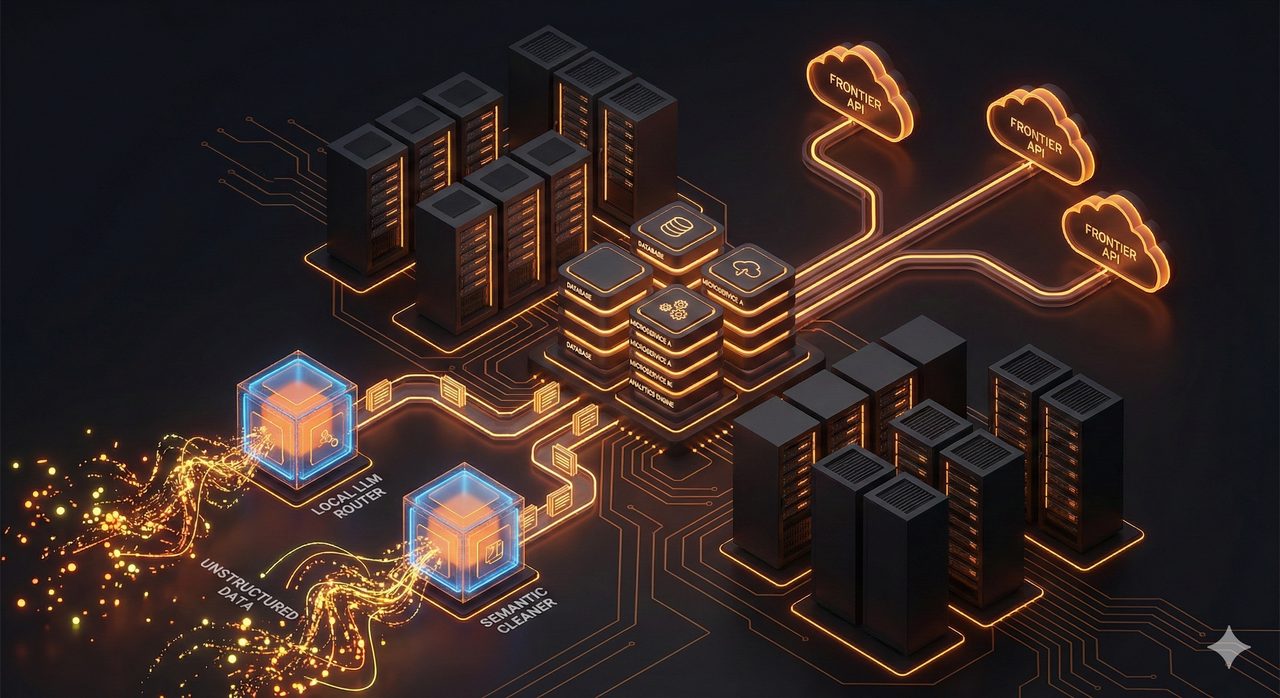
The AI-Native Backend: Beyond the Wrapper
The novelty has worn off. Latency matters. Data sovereignty matters. We are shifting from thin wrappers to true "AI-Native" backends where intelligence is the infrastructure.
> The 2026 Philosophy
"Don't use a sledgehammer to crack a nut. Don't use GPT-5-Turbo just to classify a support ticket priority. The goal is to push intelligence down the stack, closer to the metal, using specialized models."
// ARCHITECTURAL_PILLARS
01. The Semantic Router
Stop using hardcoded logic. Use a quantized local SLM (Small Language Model) to analyze intent and route requests. It's faster than an API call and infinitely more flexible than regex.
def route_request(user_query):
  # Local SLM prediction (< 20ms)
  intent = local_llm.predict(template.format(user_query))

  if intent == "BILLING":
      return billing_service.process(user_query)
  elif intent == "TECH_SUPPORT":
      return ticket_system.create(user_query)
02. Intelligent Data Hygiene
Garbage in, garbage out—but now we have intelligent disposal. Pass inputs through specialized local models to fix JSON, standardize dates, and redact PII before it ever hits your database.
03. Hybrid Orchestration
The backend acts as the traffic controller. It solves 80% of tasks locally (cheap/fast) and only escalates to expensive Frontier Models when high-reasoning is strictly required.
"The future belongs to backend engineers who understand model serving as well as they understand database indexing."